

Human-in-the-Loop AI: The Complete Production Implementation Guide
How to architect, deploy, and govern HITL systems in agentic AI workflows — from confidence threshold design to EU AI Act Article 14 compliance, with real patterns used by engineering teams shipping in 2025 and 2026.
What Human-in-the-Loop AI Actually Means in 2026
The phrase “human-in-the-loop” has been diluted to near-meaninglessness by vendor marketing. Let’s be precise: a HITL AI system is one where human judgment is structurally embedded into the decision pipeline at defined checkpoints — not just accessible after the fact, but architecturally required before certain actions complete.
This is distinct from three things it is often confused with:
- Human can appeal a decision after it’s executed
- An AI model trained by humans (that’s HITL training, not inference)
- A human monitors dashboards and can intervene “if they notice something”
- Audit trails that record what happened without enabling intervention
- The workflow cannot proceed without a human approval or correction
- Human intervention is triggered by system logic, not human vigilance
- Reviewers are given structured context, not raw model output
- Corrections feed back into model improvement automatically
The stakes of this distinction have grown dramatically. Elementum AI’s March 2026 enterprise analysis puts it sharply: as agentic AI systems gain write access to production systems, financial flows, and customer data, the blast radius of an unreviewed mistake scales proportionally. HITL isn’t a nicety; for many workflows it’s the only responsible path to deployment.
There are three primary models, each with different latency and governance implications:
| Model | How It Works | Latency Impact | Best For |
|---|---|---|---|
| Human-in-the-Loop (HITL) | Human approves or corrects before action executes | Seconds to hours | Irreversible actions, high-stakes decisions |
| Human-on-the-Loop (HOTL) | Human monitors and can intervene; system acts by default | Near-zero | High-volume, lower-stakes operations with alert thresholds |
| Human-in-Command (HIC) | Human sets policy; AI executes within policy guardrails | Near-zero | Repetitive tasks with well-defined rules and constraints |
Most production systems use all three simultaneously — routing decisions to the right tier based on risk, confidence, and reversibility.
Why This Is Urgent Right Now
The numbers tell the story of what’s actually happening in enterprise AI right now:
The underlying dynamic is straightforward: Google Cloud’s 2026 agent trends report confirms agentic AI is no longer a future concern but a present enterprise reality, with Microsoft, Oracle, and Redis all publishing specific HITL architecture documentation in April 2026 in direct response to enterprise demand.
Research cited by Beetroot AI suggests at least 30% of GenAI initiatives may be abandoned by end of 2025 due to “poor data, inadequate risk controls, and ambiguous business cases.” Weak oversight is explicitly identified as one of the leading causes. HITL addresses the oversight gap directly — but only when it’s architected properly from the start, not bolted on retrospectively.
“The difference between a HITL system that delivers governance value and one that creates bottlenecks is entirely in the design of the human side of the loop.”
— Elementum AI Engineering Research, March 2026Core Architecture Patterns
There are four production-proven patterns for embedding human oversight into AI pipelines. They differ in where the human sits relative to the AI action, and that positioning determines both the governance properties and the operational cost.
Pattern 1: Interrupt-and-Hold
The AI pipeline pauses execution at a defined checkpoint, sends a structured review request, and resumes only on human approval. This is the strongest form of HITL — no action can proceed without explicit sign-off. It’s implemented in tools like LangGraph via interrupt() calls and in agent frameworks via durable execution states.
# Simplified interrupt-and-hold pattern
async def agent_workflow(state: WorkflowState):
    result = await ai_model.propose_action(state)

    # Route based on risk score
    if result.risk_score > 0.7 or result.confidence < 0.6:
        # Serialize state, emit review event, halt execution
        review_ticket = await queue_for_human_review(
            action=result,
            context=state.context_snapshot,
            deadline_minutes=30,
            blast_radius=result.estimated_impact
        )
        # Execution resumes when reviewer acts on ticket
        approval = await review_ticket.wait_for_decision()

        if not approval.approved:
            return handle_rejection(approval.reason, state)

    return await execute_action(result)
Pattern 2: Confidence-Routed Review
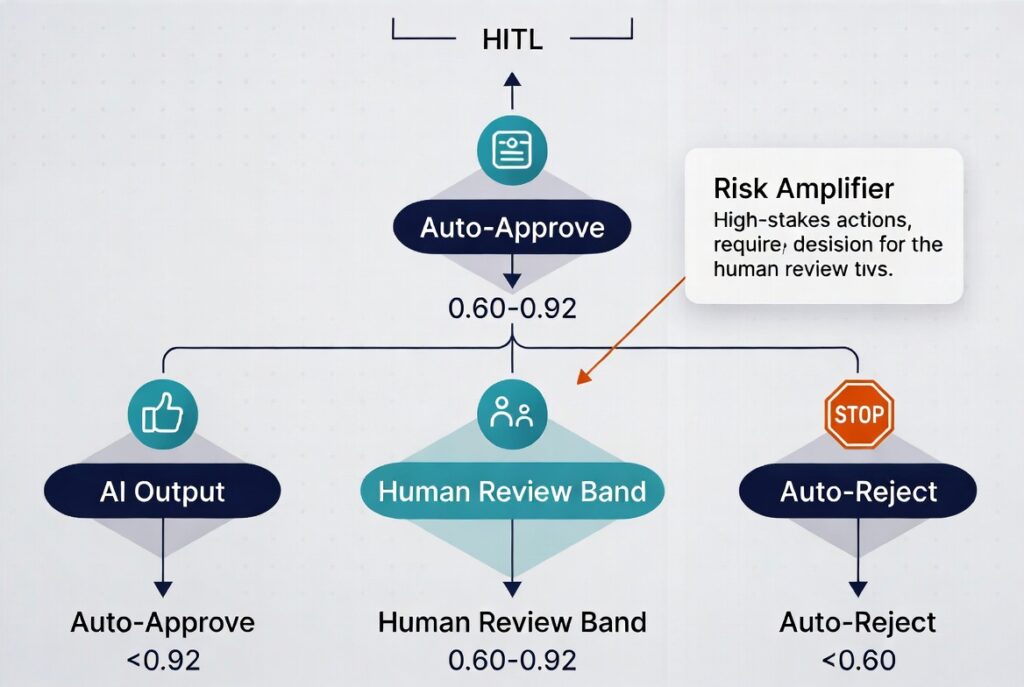
Every AI output carries a confidence score. Outputs above a high threshold proceed automatically. Outputs in an uncertainty band are routed for human review. Outputs below a low threshold are rejected outright. The routing logic is where most of the engineering complexity lives — calibrating the bands to minimize both unnecessary escalations and unchecked mistakes.
  AI Output
      │
      ├─── confidence ≥ 0.92 ──────────────→ AUTO-APPROVE
      │
      ├─── 0.60 ≤ confidence < 0.92 ──────→ HUMAN REVIEW QUEUE
      │         (+ risk score amplifier)
      │
      └─── confidence < 0.60 ──────────────→ AUTO-REJECT / ESCALATE

  Risk amplifier: even high-confidence outputs escalate if
  action_type ∈ {DELETE, FINANCIAL_WRITE, PROD_CONFIG_CHANGE}
Pattern 3: Async Batch Review
Used when real-time intervention is impractical at scale. AI processes a queue and flags a percentage for async human review. Reviewers work through a batch UI, and corrections are fed back into the model without blocking any individual request. This is the dominant pattern in document processing — invoice parsing, insurance claims triage, medical record extraction.
Pattern 4: Collaborative Generation
The AI proposes; the human edits in-context; the AI refines based on the edit. This is the most natural form for generative use cases (code review, content drafts, legal summaries) and is implemented in tools like GitHub Copilot, Cursor, and enterprise LLM writing assistants. The "loop" is conversational rather than gate-based.
The Routing Decision Framework: When to Interrupt
The most consequential design decision in any HITL system is specifying precisely which actions require human review and which don't. Too conservative and you create bottlenecks that erode trust in the system. Too permissive and the oversight is theater.
Elementum AI's enterprise research recommends asking four questions about any AI action:
Even high-confidence, seemingly low-risk actions should escalate if their failure mode is catastrophic or unrecoverable. A 98%-confident model that incorrectly deletes a customer's production database deserves no automatic approval. Design your routing logic around failure consequence, not just failure probability.
Calibrating Confidence Thresholds in Production
Confidence thresholds are where the theory of HITL meets the harsh reality of production traffic. Setting them correctly is an ongoing empirical exercise, not a one-time configuration.
Galileo's December 2025 engineering research describes confidence calibration as "a continuous process, not a one-time setup" — as your agents encounter new domains and shifting user behavior, thresholds must recalibrate to match observed error rates and reviewer capacity.
Starting Thresholds by Domain
These are documented starting points from teams currently running HITL in production. They will need tuning for your specific model, data distribution, and error tolerance:
| Domain | Auto-Approve (>=) | Review Band | Auto-Reject (<) | Rationale |
|---|---|---|---|---|
| Medical image classification | 0.97 | 0.80–0.97 | 0.80 | False negatives cost lives; calibrate conservatively |
| Loan underwriting | 0.95 | 0.70–0.95 | 0.70 | Regulatory exposure; "borderline" files to credit analysts |
| Customer refund decisions | 0.90 | 0.60–0.90 | 0.60 | Balance revenue protection with customer experience |
| Invoice data extraction | 0.88 | 0.55–0.88 | 0.55 | High volume; humans review low-confidence OCR regions |
| Infrastructure config changes | 0.99 | Any change | — | Irreversible blast radius; always requires human approval |
| Content moderation (social) | 0.92 | 0.65–0.92 | 0.65 | Appeals risk; ambiguous cases need human context |
Dynamic Threshold Adjustment
Static thresholds degrade over time. Build a feedback loop: when human reviewers consistently approve outputs that fell in your review band, your threshold is too conservative. When reviewers frequently catch errors that were auto-approved, it's too permissive. The system should surface this signal automatically and allow threshold recalibration without a deployment cycle.
# Threshold monitoring — flag for recalibration
class ThresholdMonitor:
    def weekly_health_check(self, domain: str) -> ThresholdReport:
        metrics = self.db.query_window(domain, days=7)

        # Signal: reviewers rubber-stamping → threshold too low
        approval_rate = metrics.human_approvals / metrics.escalations
        if approval_rate > 0.95:
            return ThresholdReport(
                signal="RAISE_AUTO_APPROVE_THRESHOLD",
                current=self.thresholds[domain],
                suggested=min(self.thresholds[domain] + 0.02, 0.99)
            )

        # Signal: high override rate → auto-approves need tighter calibration
        override_rate = metrics.post_approval_corrections / metrics.auto_approvals
        if override_rate > 0.08:
            return ThresholdReport(
                signal="LOWER_AUTO_APPROVE_THRESHOLD",
                current=self.thresholds[domain],
                suggested=max(self.thresholds[domain] - 0.03, 0.5)
            )
HITL for Agentic AI Workflows
Agentic AI introduces a category of challenges that confidence thresholds alone cannot address. An agent that can chain multiple tool calls, maintain state across sessions, and spawn subagents creates compounding error risk — a single unapproved intermediate action can cascade into irreversible downstream effects.
Strata's 2026 agentic identity research identifies two patterns that consistently derail oversight programs in agentic systems:
Automation complacency: The more reliable a system appears, the less vigilant its human overseers become. Teams stop questioning outputs and begin rubber-stamping. This is documented across aviation, nuclear operations, and increasingly, enterprise AI review workflows. The antidote is not more alerts — it's structured challenge-and-response protocols that prevent passive approval.
Unpracticed teamwork: Without deliberate rehearsal, handoffs between AI agents and human reviewers become ambiguous. Escalation paths go untested until they fail under real-world stress. Teams need to exercise the human side of the loop with the same rigor they apply to model testing.
Implementing Approval Gates in Agent Chains
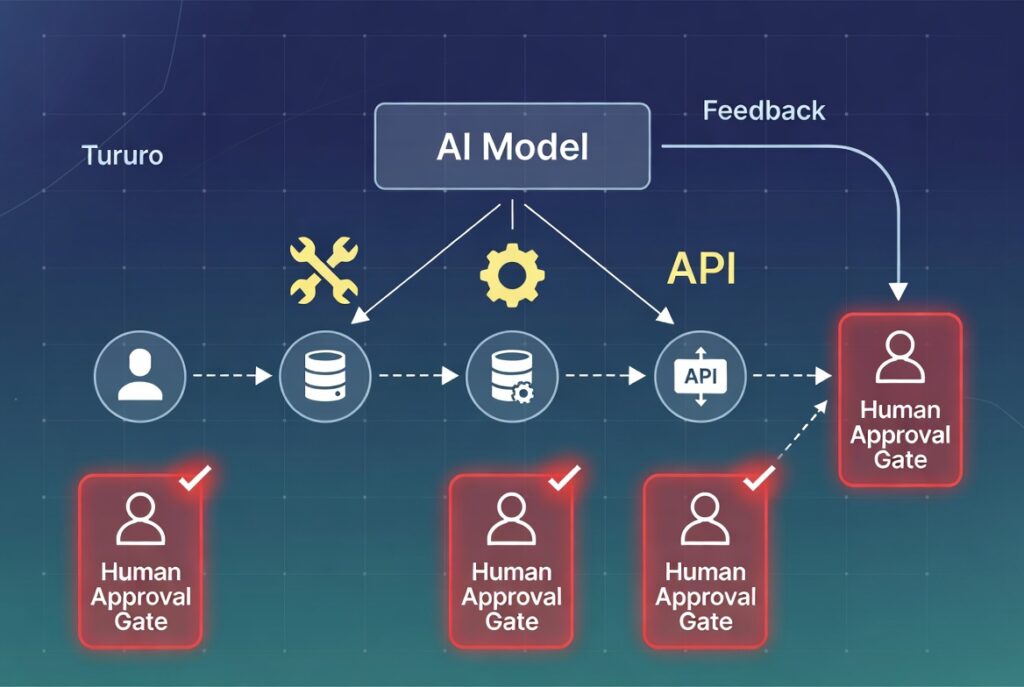
Permit.io's June 2025 implementation guide outlines a policy-driven approach using three components:
- Interrupt gates:
interrupt()calls that halt the agent and await an externally delivered approval before resuming execution — not a polling loop, but true async suspension with durable state. - Policy-driven permissions: All approval logic managed via a policy engine (not hardcoded in agent logic), so rules can be updated without redeployment.
- Audit trail per tool call: Every tool invocation is logged with the approval chain — who approved what, when, under which policy version.
Route to human review whenever an agent: (1) proposes an action with write access to production systems, (2) encounters an input outside its demonstrated training distribution, (3) requests a scope expansion beyond its initial authorization, or (4) produces a confidence score that falls unexpectedly given the input type. Sudden scope expansion — an agent quietly acquiring more permissions than it needs — is a particularly dangerous signal that should always trigger interruption.
Implementing Challenge-and-Response Approvals
Replace simple "Approve/Reject" buttons with structured challenge-and-response. The reviewer must positively acknowledge each item in a checklist before approval is accepted:
- Intent is clearly stated and matches the originating request
- Data lineage and input sources are verified
- Permission chain is within the authorized scope
- Estimated blast radius (impact if wrong) is acceptable
- Rollback plan exists and has been reviewed
- No unexpected scope expansion beyond initial authorization
This structure prevents automation complacency by requiring active cognitive engagement rather than passive approval. Strata's research documents this as one of the five most effective practices adapted from aviation human-factors engineering.
Designing the Human Review Interface
The interface a reviewer works in is not a UX concern — it's an architecture concern. A poorly designed review interface makes HITL a bottleneck without a governance payoff. Elementum AI's enterprise research is unambiguous: "When the human side of the loop is an afterthought, buried in clunky interfaces with no context, reviewers become rubber stamps and the governance value collapses."
What Every Review Interface Needs
| Element | Why It Matters | Common Failure Mode |
|---|---|---|
| Structured context summary | Reviewer must understand what the AI is proposing and why, without reading raw model output | Showing raw JSON dumps or full model outputs — reviewers skip or rubber-stamp |
| Confidence score + uncertainty signal | Reviewer needs to know why this was escalated, not just that it was | Confidence displayed with no explanation of what caused the low score |
| Blast radius indicator | Calibrates how much attention the reviewer should invest | Treating all review items as equally urgent regardless of impact |
| Similar past decisions | Reduces cognitive load; builds consistent decision-making across reviewers | Reviewers making inconsistent decisions on similar cases |
| Correction workflow (not just approve/reject) | Allows reviewer to fix the AI's output, not just approve or block it | Forcing rejection + manual re-submission when a small edit would suffice |
| Reason capture on rejection | Rejection reasons become training signal for model improvement | Free-text fields ignored; no structured taxonomy for rejection reasons |
| SLA deadline visibility | Prevents stale review items causing downstream workflow failures | Items aged out of queue silently, causing operational incidents |
Active Learning and the Feedback Loop
A HITL system that doesn't improve the model is an operational tax with no equity. The feedback loop — from human correction to model update — is what transforms HITL from a cost center into a compound investment.
The mechanism described by Roboflow's February 2026 production patterns is elegant in its simplicity: the model identifies uncertainty, humans correct those cases, and corrections improve the next model version. The loop is: flag → review → correct → retrain → threshold recalibrate → repeat.
Implementing Structured Feedback Collection
Galileo's implementation research emphasizes that feedback interfaces must capture three things alongside each correction:
Natural language reasoning: Why did the reviewer correct this? This prose becomes training signal for evaluation prompts, not just fine-tuning data. Teams using Galileo's Autotune feature report that expert corrections can be automatically converted into more accurate evaluation rubrics.
Categorical rejection taxonomy: Structured categories (model hallucination, data quality, ambiguous input, policy violation, edge case) enable pattern analysis across thousands of corrections. A cluster of "ambiguous input" rejections at a particular confidence band signals a data labeling problem, not a threshold problem.
Version tracking: Every correction is linked to the model version, threshold configuration, and policy version at the time of the review. This enables before/after comparison when a model update is deployed.
Active Learning Strategy
Active learning — selectively querying humans for labels on the most informative examples — is the bridge between HITL and model improvement. The key principle from Tredence's HITL research: incorporate active learning only when the model's confidence is genuinely low or uncertain. This keeps human effort focused on the cases where their input has maximum marginal value.
Teams that instrument their HITL feedback loop correctly see a measurable decline in escalation rate over time — as the model learns from corrections, it handles previously uncertain cases autonomously. A well-operated HITL system should be designed to make itself less necessary for the cases it encounters repeatedly, while staying vigilant for genuinely novel situations.
EU AI Act Article 14: What Compliance Actually Requires
The EU AI Act's human oversight requirements, codified in Article 14, represent the most concrete regulatory HITL mandate currently in force. For any organization operating high-risk AI systems in the EU — which includes AI in hiring, credit, education, critical infrastructure, law enforcement, and biometrics — Article 14 compliance is not optional.
The IAPP's February 2026 analysis summarizes the core obligation: high-risk systems must be designed so "natural persons can oversee their functioning, ensure that they are used as intended, and that their impacts are addressed over the system's lifecycle."
The Four Article 14 Requirements in Practice
Effective oversight capability
The system must be technically designed to allow oversight, not just theoretically allow it. Passive monitoring dashboards without intervention capability do not satisfy this requirement.
- Interrupt and halt mechanisms accessible to designated oversight personnel
- Real-time visibility into AI decision-making, not just post-hoc logs
- Clear UI indicating when the system is operating autonomously vs. supervised
Understanding of capacities and limitations
Oversight personnel must demonstrably understand what the AI can and cannot do — specifically including its tendency to fail on edge cases and its susceptibility to automation bias.
- Documented training program for reviewers covering model limitations
- Regular calibration exercises with known-difficult cases
- Automation bias awareness training with documented sign-off
Intervention when appropriate
The system must provide mechanisms, instructions, and tools that help the oversight person decide when and how to intervene — not just the ability to intervene, but actionable guidance.
- Escalation triggers documented in operational runbooks
- Clear criteria for when a decision requires human review vs. autonomous execution
- Override documentation requirements tied to accountability records
Automation bias safeguards
Oversight personnel must maintain awareness of their tendency to over-rely on AI outputs. This is explicitly required under Article 14 and is the hardest to operationalize — it requires active system and process design, not just disclosure.
- "Two-factor judgment" on critical actions: independent review or counter-model sanity check
- Challenge-and-response checklists that prevent passive approval
- Periodic insertion of "test cases" (known errors) into review queues to measure reviewer vigilance
A May 2026 TechPolicy.Press analysis notes that Article 14's "stop button" requirement was designed for systems with a clearly defined "safe state" — an assumption that breaks down for agentic AI that can execute irreversible multi-step actions. The article notes: "Agents interacting with external systems — placing orders, executing transactions — may take actions that are impossible to undo, with no clearly defined 'safe state' to return to." Until harmonized standards for agentic AI oversight are published, teams should design for the spirit of Article 14 rather than its literal text: maximize actionable intervention points across the execution chain, not just at the start and end.
The 8 Anti-Patterns That Kill HITL Systems
HITL as a post-hoc add-on
Building the AI system first, then adding review steps at the edges. Real HITL must be a first-class architectural constraint from day one, not a layer applied over an autonomous system.
Uniform escalation (no risk stratification)
Routing all uncertain outputs to the same queue regardless of consequence. An uncertain invoice line-item and an uncertain production database deletion do not deserve the same review intensity or SLA. Risk stratification is the prerequisite for any scalable HITL system.
Treating reviewers as a rubber-stamp layer
Designing the review interface so quickly that approvals become the default behavior. If the path of least resistance for a reviewer is to approve without reading, the governance value is zero. Every interface element should require active engagement.
Static confidence thresholds
Setting thresholds at launch and never recalibrating. As model behavior shifts with new data, thresholds drift out of alignment with actual error rates. Threshold monitoring should be an automated, scheduled process.
No feedback loop from corrections to training
Collecting human corrections without feeding them back into the model or evaluation system. This is the most expensive anti-pattern — you're paying the operational cost of human review without capturing the learning value.
Full-AI or full-human framing
Treating the problem as "should we automate this or not?" instead of "where exactly does human judgment add the most value?" As one HITL practitioner put it: "AI handling data collection while humans make strategic decisions" is the sweet spot — not binary replacement.
Untrained reviewers
Assigning people to review AI outputs without training them on the model's known failure modes, the review criteria, or the annotation guidelines. Just as models are trained on data, human contributors must be trained on the same standards the model is evaluated against.
No escalation path above the reviewer
A reviewer who encounters something they can't confidently decide on needs a clear escalation path — to a senior reviewer, a domain expert, or a policy owner. Without it, genuinely ambiguous cases get approved by default because the reviewer has no other option.
Phased Implementation Roadmap
Beetroot AI's implementation research consistently recommends a staged approach: "start with a single, high-impact area, learn from the results, and proceed from there." Large-scale simultaneous HITL rollouts across multiple workflows create coordination failures and obscure the causal signal needed to improve thresholds.
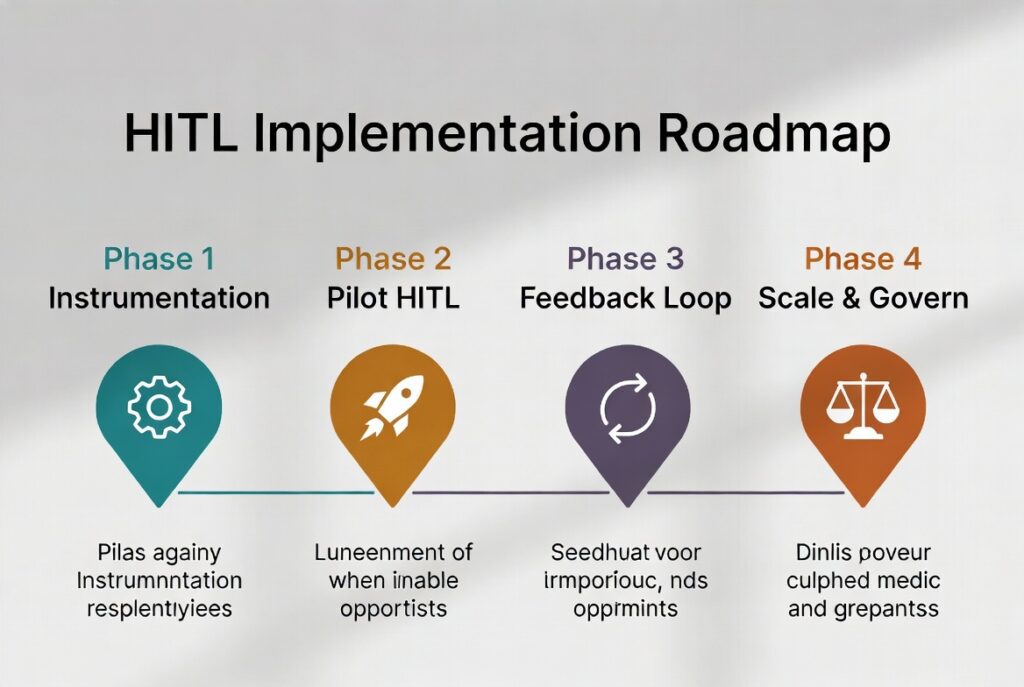
Phase 1 — Instrumentation (Weeks 1–3)
Before any HITL gates, build the observability layer. You cannot calibrate what you cannot measure.
- Log confidence scores, latencies, and decision outcomes for every AI action
- Map all AI actions to reversibility and blast-radius categories
- Identify the single highest-impact workflow for pilot
- Define success metrics: escalation rate, reviewer accuracy, correction-to-retrain latency
Phase 2 — Pilot HITL (Weeks 4–8)
Deploy HITL on the selected pilot workflow with conservative thresholds and a small reviewer pool.
- Implement interrupt-and-hold for any irreversible action in the pilot scope
- Build the reviewer interface with structured context, confidence display, and reason capture
- Train reviewers on model limitations and challenge-and-response protocols
- Weekly threshold analysis and calibration sessions
Phase 3 — Feedback Loop Activation (Weeks 9–14)
Connect reviewer corrections to the model training pipeline. This is when HITL starts returning its investment.
- Automated ingestion of structured corrections into the evaluation dataset
- Threshold recalibration tooling with weekly reports
- Active learning integration: model flags its most uncertain cases for priority review
- Monthly escalation rate trend review against baseline
Phase 4 — Scale and Govern (Week 15+)
Roll HITL patterns from the pilot to additional workflows, with documented policies and a governance structure.
- HITL policy documentation per workflow type (thresholds, SLAs, escalation paths)
- EU AI Act Article 14 compliance audit for any high-risk AI system classifications
- Reviewer simulation exercises for agentic workflows (test the handoffs before they happen in production)
- Cross-workflow dashboard: escalation rates, reviewer performance, model improvement trend
KPIs and Operational Metrics
A HITL system is only governable if it's measurable. These are the metrics that teams operating HITL in production track to determine whether their system is healthy, degrading, or improving:
| Metric | What It Signals | Target / Alert |
|---|---|---|
| Escalation rate | % of AI outputs routed to human review | Track trend; sharp increase = model drift or data shift |
| Reviewer approval rate | % of escalated items approved without change | >95% = threshold too conservative; recalibrate upward |
| Correction rate | % of items approved with correction vs. straight approval | Track by confidence band to find model weak spots |
| Post-approval incident rate | % of auto-approved items that later required manual remediation | >3–5% = threshold too permissive; lower auto-approve floor |
| Time-to-review (P50/P95) | How long it takes a reviewer to process an item | P50 should reflect domain complexity; P95 > SLA = staffing issue |
| Reviewer inter-rater agreement | Do different reviewers make the same decisions on the same inputs? | <80% agreement = unclear annotation guidelines or ambiguous criteria |
| Correction-to-training latency | How quickly human corrections reach the model as training signal | Target: <1 week for active learning; <1 sprint for fine-tuning |
| Escalation rate trend (weekly) | Is the model improving? Escalation rate should decline over time as corrections accumulate | Flat or rising trend after 8 weeks = feedback loop broken |
If you track only one number, track the post-approval incident rate. It measures the most dangerous failure mode: outputs that passed HITL review and still caused harm or required remediation. A rising post-approval incident rate means your human review is not adding the governance value you're paying for — and that demands immediate investigation of reviewer interface design, training, and workload.
Primary Sources & Further Reading
- Elementum AI: Human-in-the-Loop Agentic AI — When You Need Both (March 2026)
- Strata: Practicing the Human-in-the-Loop — Agentic Identity Patterns (May 2026)
- Permit.io: HITL for AI Agents — Best Practices, Frameworks & Demo (June 2025)
- Galileo: Building Human-in-the-Loop Oversight for AI Agents (December 2025)
- Roboflow: HITL for High-Stakes AI — Confidence Routing Patterns (February 2026)
- EU AI Act Key Issue 4: Human Oversight (Article 14)
- TechPolicy.Press: The EU AI Act is Not Ready for Agents (May 2026)
- IAPP: EU AI Act Shines Light on Human Oversight Needs (February 2026)
- WitnessAI: Human-in-the-Loop AI — Benefits, Use Cases & Best Practices (February 2026)
- Aokumo AI: HITL Is Not a Weakness — It's the Architecture Everyone Is Scrambling to Build (April 2026)
Continue Reading on Trendix.tech
- AI Agents & Multi-Agent Systems: The Definitive 2026 Guide
- LangGraph vs CrewAI vs OpenAI Agents SDK vs AutoGen (2026): The Definitive Comparison
- Explore All AI Trends & Agent Workflows →
More agentic AI architecture and tooling deep-dives from the Trendix team.
Building Your First Production LangGraph Agent – Step-by-Step Tutorial
7 Production Multi-Agent Design Patterns
NotebookLM for Researchers: A Deep Dive Into the Most Underused AI Tool
AI Agents & Multi-Agent Systems: Everything Changes This Year
AI Agent Use Cases by Business Function:The 2026 Prioritization Guide
Agentic Workflows: How AI Systems Are Actually Taking Over Knowledge Work