

Agentic Workflows: How AI Systems Are Actually Taking Over Knowledge Work in 2025–2026
The gap between “AI assistant” and “AI that does the work” is collapsing. Here’s how agentic workflows are built, where they’re already delivering real results, and what separates the successful deployments from the expensive failures.
There’s a specific moment that tends to convince skeptics. Someone shows them an AI system that doesn’t just answer a question — it receives a goal, breaks it apart, calls a database, writes a summary, sends an email, waits for a response, then follows up. All without a human touching it between steps. That’s usually when it clicks: this isn’t a smarter chatbot. This is something structurally different.
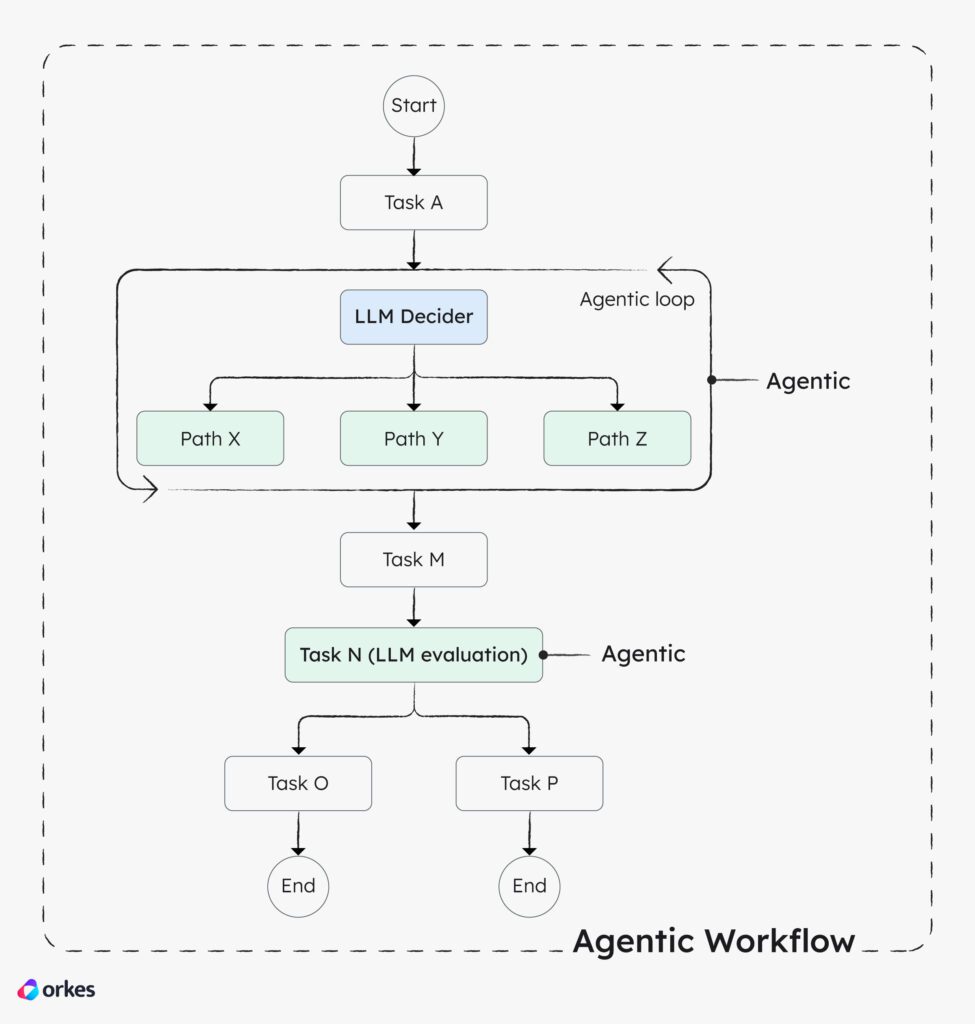
Agentic workflows are that structural difference, made concrete. The phrase gets used loosely — sometimes to mean any LLM with a tool, sometimes to mean fully autonomous digital employees — but there’s a reasonably precise definition worth holding onto. An agentic workflow is a multi-step, dynamic process that orchestrates LLM reasoning, tool calls, external APIs, and conditional logic in a way that can branch, loop, and adapt based on what it finds along the way. It’s not just automation. It’s automation that can figure out what to do next.
This post is a serious attempt to explain how all of that actually works — the architecture, the patterns, the real results, and the honest failure rates. No sponsored content, no vendor talking points stitched together. Just what we know from the data as of mid-2026.
1. What Actually Makes a Workflow “Agentic”?
The confusion about this term is understandable. “Agentic AI” and “AI agents” get used interchangeably, which makes things muddier than they need to be. The distinction worth drawing is between a workflow and an agent.
An AI agent is a system — typically a language model enhanced with tools and memory — that perceives its environment, decides what to do, and acts. An agentic workflow is the architecture that governs how one or more agents operate: what happens in what order, when to branch, when to loop, when to call a human, and when to stop.
Think of it this way: an agent is a worker; an agentic workflow is the operating procedure that determines how that worker (or team of workers) actually functions. You can have a capable agent operating inside a badly designed workflow and get terrible results. The design of the workflow — the orchestration — matters as much as the capability of the underlying model.
Researchers and practitioners tend to agree on three things that make something genuinely agentic rather than just scripted automation: (1) Goal-directed behavior — the system works toward an objective rather than executing a fixed script; (2) Tool use and environmental interaction — the ability to call APIs, search the web, read files, write code, interact with UIs; and (3) Adaptive execution — the system changes its approach based on what it encounters, rather than following a predetermined path regardless of context.
What separates 2025 from earlier attempts at autonomous AI is that the foundation — the models themselves — got dramatically better at all three. The jump from GPT-3 to GPT-4 was impressive for text quality; the jump to models like Claude Opus 4, GPT-5, and Gemini 2.x was about reliability under tool use and multi-step reasoning. That reliability is what makes production deployments feasible rather than experimental.
“In 2025, leading models don’t just chat. They plan steps, call tools, browse, and even operate a computer — which makes goal-seeking behavior practical.” — Svitla Systems, Agentic AI Trends 2025
The practical implication: agentic workflows became production-viable around 2024–2025 not because the idea was new, but because the models finally got reliable enough to be trusted with multi-step tasks at scale. Autonomous agents had been a research topic for decades. The implementation gap closed when foundation model capability crossed a reliability threshold that allowed errors to be caught and corrected rather than silently compounding.
2. The Core Architecture: How Agentic Workflows Are Built
Strip back the frameworks and the vendor branding, and most agentic systems have the same five layers. Understanding what each layer does helps enormously when evaluating tools or diagnosing why something isn’t working.
| Layer | What It Does | Key Decisions | Common Failure Modes |
|---|---|---|---|
| Foundation Model(s) | Reasoning, planning, language understanding, code generation | Model selection by task, cost/quality tradeoff | Hallucination, tool-use errors, reasoning drift over long contexts |
| Tool Registry | APIs, file systems, browsers, code executors, databases the agent can call | Scope of tools, permission design, sandboxing | Over-privileged tools, cascading errors, rate limiting |
| Memory System | Short-term (context window), working memory, long-term (vector DB/knowledge base) | What to persist, when to retrieve, context compression | Context overflow, stale retrieved data, memory poisoning |
| Orchestration Layer | Defines the workflow: what runs when, how agents hand off to each other, branching logic | Graph vs. chain vs. hierarchical routing, retry logic | Infinite loops, orchestrator bottlenecks, unclear handoff conditions |
| Observability & Governance | Tracing, logging, human-in-the-loop checkpoints, evaluation, audit trail | What requires human approval, evaluation metrics, alert thresholds | Silent failures, undetected drift, no rollback capability |
The orchestration layer is where most of the interesting architectural decisions happen. A few years ago, most practitioners built this with LangChain pipelines that were essentially linear chains: do A, then B, then C. That worked for simple tasks but broke down quickly when you needed conditional logic, parallelism, or error recovery.
The current state of the art uses graph-based orchestration — where nodes represent agent steps or decisions, and edges represent transitions. This lets you model loops, branches, parallel execution, and human handoffs in a way that’s explicit and debuggable. LangGraph is the most widely deployed implementation of this pattern; Temporal.io has gained serious traction in enterprise settings that need durable execution guarantees (it originated at Uber and handles things like retry logic and state persistence across failures natively).
One pattern that catches teams out: the orchestrator-as-bottleneck. When you have a single “brain” agent coordinating many subagents, that orchestrator’s context window fills up with results, its quality degrades, and the whole system quietly gets worse over time. Production-grade systems solve this by keeping orchestrator state lean — passing summaries rather than full outputs between agents, and writing intermediate results to persistent storage rather than accumulating them in the orchestrator’s context.
3. The 7 Design Patterns That Matter Most
This is where the rubber meets the road. There are roughly seven patterns that cover the vast majority of real-world agentic workflows. Knowing which pattern to reach for — and which to avoid — is one of the most useful things you can internalize.
1. Single-Agent (Monolithic)
One agent handles the entire task end-to-end. Best for well-scoped, lower-complexity tasks where latency matters. Simple to debug. Gets unwieldy when tasks require deep specialization across domains.
2. Orchestrator–Worker
A coordinator agent decomposes the goal and delegates subtasks to specialized workers. Strong for parallelizable tasks: web scraping, batch processing, distributed test execution. The most common enterprise architecture today.
3. Reflection & Self-Critique
The agent reviews and critiques its own output before finalizing. Dramatically improves quality on high-stakes outputs — legal drafts, code reviews, financial summaries. Adds latency and token cost, so use selectively.
4. Routing
An intelligent classifier directs requests to specialized sub-agents or models based on query type. Optimizes for both cost and quality by avoiding over-engineering every request through the most capable (and expensive) model.
5. Collaborative Multi-Agent
Peer agents work as equals, debating or combining perspectives. Common in investment analysis, adversarial code review, or any domain where cross-checking by independent “opinions” adds value.
6. Tool-Use / Agentic Process Automation
The agent interacts with external systems via defined interfaces — APIs, browsers, file systems, databases. Replaces traditional RPA when tasks require reasoning to handle exceptions and edge cases.
7. Human-in-the-Loop (HITL)
The agent pauses at defined checkpoints and hands off to a human for approval or judgment. Essential for high-stakes decisions. Not a fallback — it’s a first-class design choice that extends trust in production.
Patterns are frequently combined. A common production architecture: Routing → Orchestrator–Worker → Reflection → HITL at the output boundary.
The practical question most teams face isn’t “which pattern?” but “how much autonomy?” This is genuinely hard, and there’s no universal answer. High-stakes domains (healthcare, finance, legal) almost always need HITL checkpoints even when the agent is highly accurate — because errors in those domains have asymmetric consequences. High-volume, lower-stakes domains (email triage, data extraction, research summarization) can run with more autonomy because the cost of an occasional error is low and human review doesn’t scale.
When deciding how much autonomy to grant an agent, ask: “If this action is wrong, is it reversible?” Read-only operations (searching, summarizing, retrieving) can be fully automated. Actions with real-world consequences (sending an email, making a payment, modifying a database) warrant a confirmation step, at least until the agent’s accuracy on that specific task is validated over time.
4. Framework Landscape: LangGraph, AutoGen, CrewAI, and the Rest
The framework space has matured considerably. A year ago it felt like a new library appeared every week; now there’s a clearer sense of which tools are earning their place in production systems versus which are interesting demos. Here’s where things stand as of mid-2026:
One protocol worth understanding separately: Model Context Protocol (MCP). MCP is an emerging standard — supported by Anthropic and increasingly by others — that gives agents a standardized way to understand and interact with tools in their environment. Think of it as a universal adapter layer for agentic tool use, similar to what USB standardization did for hardware. Its adoption is accelerating fast, and building against MCP-compatible tools significantly reduces future integration overhead.
Similarly, Agent-to-Agent (A2A) interoperability — now actively being developed by Microsoft — is addressing what happens when agents from different vendors need to collaborate. This is still early, but it’s the right problem to be solving. Fragmented agent ecosystems create enormous coordination overhead in real enterprise environments.
5. Real-World Case Studies with Verified ROI
This is where a lot of writing on agentic AI falls down. Vague claims of “dramatic productivity improvements” are useless. What follows are deployments with named companies, specific functions, and quantified outcomes — all from verified sources published in 2025–2026.
Klarna deployed a customer service AI agent that, by mid-2025, was handling the equivalent workload of 853 full-time customer service employees. The agent handled queries in multiple languages, resolved most issues without escalation, and operated at a fraction of the per-interaction cost of human agents. The company reported $60 million in cost savings.
There’s an honest footnote here: Klarna subsequently brought back some human agents for emotionally complex or high-stakes queries — recognizing that the AI couldn’t reliably handle situations requiring empathy and nuanced judgment. This is a mature finding, not a failure. The right design uses AI for the 80–90% of interactions that are routine, and humans for the ones that genuinely require a person.
JPMorgan runs over 450 AI use cases in production daily. Within investment banking specifically, AI agents now generate pitch book presentations in roughly 30 seconds — tasks that previously took junior analysts hours of manual work. The system pulls live data, applies templates, and formats outputs to bank standards.
Separately, an agent-based contract review system reduced legal processing costs by $5 million. The scope isn’t narrow: Morgan Stanley’s parallel DevGen.AI deployment reviewed over 9 million lines of legacy code and reclaimed approximately 280,000 developer hours for their team of 15,000.
SoftBank built an AI-agent-powered sales operating model using Dataiku. Sales conversations are captured, automatically structured, linked to CRM opportunities, and surfaced as action items — without sellers doing any manual data entry. The system was a finalist for the 2025 Dataiku Frontrunner Award for Best Agentic AI Use Case.
The efficiency gain translates to roughly 20 hours saved per seller per month — and with a large enough sales team, that’s over 250,000 hours reclaimed annually. More importantly, the time shifts from administrative overhead to customer-facing work, which has direct revenue implications.
Ford is using AI agents to accelerate vehicle design and engineering — transforming processes that previously took hours into operations that take seconds. The agentic workflow chains together tasks that were previously sequential and manual: sketch-to-3D rendering, stress analysis, simulation, and testing can now run in a connected pipeline where outputs from one step automatically feed the next.
This isn’t just faster — it changes what’s feasible at the design stage. Engineers can run far more design iterations in the same timeframe, which fundamentally affects product quality and time-to-market.
6. What the Numbers Actually Show: ROI and Timelines
There’s a wide range of ROI claims in circulation, and it’s worth being clear about what the data actually shows — and where you should be skeptical.
| Metric | What the Data Shows | Source / Confidence |
|---|---|---|
| Average reported ROI | 171% (U.S. enterprises: 192%) | High Landbase survey, 2025 |
| % achieving ROI within Year 1 | 74% (Google Cloud ROI Report, 2025); 41% per Gartner/Bain (tighter definition) | Mixed Methodology varies significantly |
| Median payback period — customer service | 4.1 months | High Bain Agentic AI Benchmark 2026 |
| Median payback — marketing ops | 6.7 months | High Bain Agentic AI Benchmark 2026 |
| Median payback — engineering | 9.3 months | High Bain Agentic AI Benchmark 2026 |
| Hours saved per knowledge worker per week | Median 6.4 hrs (McKinsey); senior practitioners: 10–12 hrs | High McKinsey Global AI Survey 2026 |
| Cost per resolved customer service ticket | $0.46 (AI) vs. $4.18 (human) — roughly 9x cheaper | High Forrester TEI, 2026 |
| Deployments that never reach payback | 19% in 2026 (down from 34% in 2025) | High Gartner; trend is encouraging |
| Projects expected to fail by 2027 | 40% — due to high costs, unclear value, inadequate risk controls | Medium Gartner projection |
The honest read: ROI numbers are real but highly variable. The difference between the top quartile and bottom quartile of deployments isn’t mostly about which LLM you use. It’s about whether you picked the right workflow to automate, whether your data was clean enough to support it, and whether you built the evaluation and observability infrastructure to know when the agent is drifting or failing.
That last point — the 19% that never reach payback falling from 34% in a single year — is actually the most interesting number in the table. It suggests that the main thing improving outcomes isn’t model capability (which is narrowing between top providers anyway). It’s the maturation of tooling around evaluation and integration. Vendor agents now ship with eval harnesses and integration templates that custom builds had to invent from scratch two years ago.
7. Why 40% of Projects Still Fail (and How to Not Be One of Them)
Gartner’s projection that 40% of agentic AI projects will be aborted by 2027 is alarming on first read, but it becomes less surprising once you look at what’s actually causing failure. It’s not primarily model error. The top failure categories are more prosaic:
| Failure Category | Prevalence | What It Usually Looks Like |
|---|---|---|
| Inadequate data quality / integration | Primary driver | Agent can reason correctly but acts on stale or wrong data. Results look convincing but are unreliable. |
| No evaluation infrastructure | Very common | Teams build working agents but can’t prove they’re working. No metrics = no confidence = no scaling. |
| Platform sprawl / poor interoperability | Common | Agents isolated in silos can’t access the systems they need. 63% of executives cite this as a growing concern. |
| Unclear business value / wrong workflow chosen | Common | Automating the wrong thing. High technical success, zero business impact. |
| Inadequate governance / risk controls | Common | Agent does something it shouldn’t, organization isn’t set up to detect or respond. Escalates to incident. |
| Cybersecurity vulnerabilities | Growing | Prompt injection via external content, over-privileged tool access, data exfiltration through agent actions. |
The uncomfortable truth is that most agentic AI failures are not AI problems. They’re data problems, organizational problems, and process problems that were already there before the AI arrived. The agent just makes them visible faster and at greater scale.
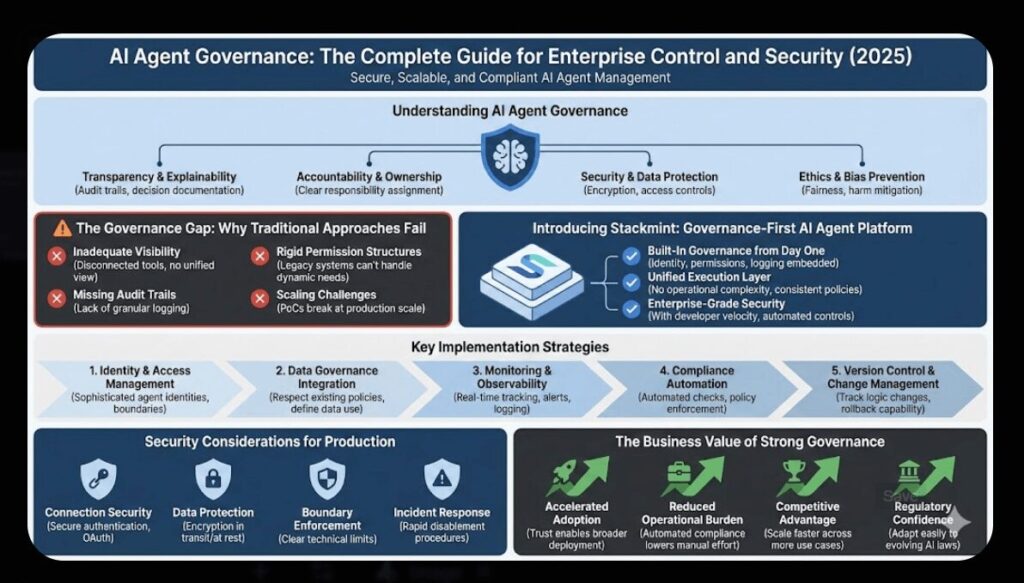
When agents browse the web, read emails, or process external documents, they’re exposed to content that could contain adversarial instructions designed to hijack their behavior. This is prompt injection, and it’s a real production vulnerability. The OWASP ATLAS threat model covers it in detail. Mitigation requires sandboxing external content carefully and building agents that treat data from the environment differently from instructions from the operator.
8. Governance, Security, and Human Oversight
Governance is the part that organizations tend to under-invest in until they have a problem. Given that 75% of technology leaders now list governance as their primary concern when deploying agentic AI, it’s worth being specific about what a real governance framework includes — and what “human-in-the-loop” actually means in practice.
Deloitte’s 2026 research on agentic AI strategy frames this well: agents may come to be seen as a silicon-based workforce that complements the human workforce. That framing isn’t just poetic — it has real implications for how you manage them. You wouldn’t deploy a new team of contractors without defining their scope of authority, escalation procedures, and performance metrics. The same logic applies to agents.
Core Governance Elements
- Minimal footprint principle: Grant agents only the permissions they need for the task at hand. An agent drafting emails doesn’t need write access to production databases.
- Explicit HITL checkpoints: Define in advance which actions require human approval, and make these checkpoints non-bypassable rather than advisory.
- Comprehensive audit trails: Every agent action, tool call, and decision should be logged with enough context to reconstruct what happened and why.
- Version control for prompts and models: Treat system prompts like code. Changes should go through review, have rollback capability, and be tracked against performance metrics.
- Evaluation harnesses: Automated testing against known-good examples, covering both task success and safety properties.
- Incident response procedures: What happens when an agent does something wrong? Who gets alerted, how is it contained, and how is root cause determined?
The regulatory landscape is moving too. The EU AI Act’s provisions around high-risk AI systems increasingly apply to agentic deployments in healthcare, finance, and public services. Organizations in those sectors should be treating compliance not as a future problem but as a constraint to design around from the start.
9. The Readiness Checklist: Is Your Organization Ready?
Before committing significant resources to an agentic workflow deployment, it’s worth being honest about where your organization actually stands. Most teams overestimate their data readiness and underestimate how much the observability and governance work will cost.
Organizational Readiness Assessment
| Dimension | Not Ready | Partially Ready | Ready |
|---|---|---|---|
| Data Quality | Siloed, inconsistently formatted, access-restricted data | Reasonably clean data in key systems, some access gaps | Clean, accessible, well-documented data with APIs |
| Process Clarity | The workflow you want to automate is poorly defined even for humans | Core process is documented; edge cases are fuzzy | Process is well-understood with clear exception handling |
| Evaluation Capability | No clear definition of “good output” | Qualitative success criteria, some human review | Quantitative metrics, test suites, automated eval |
| Security Posture | No consideration of agent-specific risks | Aware of risks, partial controls | Threat-modeled, sandboxed tools, incident procedures |
| Change Management | No stakeholder buy-in; no training plan | Leadership support, limited team preparation | Champions identified, training underway, feedback loops active |
If you’re mostly in the “not ready” column, the right move isn’t to slow down indefinitely — it’s to build the foundations before deploying at scale. A two- to three-month data quality and process documentation sprint before launching an agent project consistently outperforms jumping straight to deployment and then discovering problems in production.
The most consistent finding across enterprise deployments: take one high-value use case to production first, measure it rigorously, then scale to additional workflows once multi-user authorization and governance are proven. Breadth-first deployment — trying to agentize everything at once — is the pattern that most frequently leads to the “abandoned due to complexity” outcome Gartner is projecting.
10. Where This Is Heading: 2026 and Beyond
A few trends worth tracking closely — these aren’t speculative futures, they’re already visible in the data and in early deployments.
From Multi-Agent to Single Highly-Capable Agent
IBM’s research team makes an interesting prediction: as individual models become more capable, we’ll see a pendulum swing back from multi-agent orchestration toward single-agent systems that can handle end-to-end tasks without coordination overhead. This isn’t happening yet — multi-agent architectures dominate 66.4% of current implementations — but it’s the direction that model capability improvements are pointing toward. Worth watching.
Low-Code / No-Code Agentic Building
The barrier to building agents is collapsing. Teams that once needed ML engineers can now deploy agents through visual builders in 15–60 minutes. By 2026, roughly 40% of enterprise software is expected to be built using natural-language-driven approaches. This democratization is real, but it also means that governance frameworks become more urgent — more agents built faster means more potential for poorly-governed agents doing unexpected things.
Guardian Agents
Gartner projects that “guardian agents” — agents whose job is to monitor other agents, verify outputs, flag anomalies, and enforce policies — will capture 10–15% of the agentic AI market by 2030. It’s a telling development. As agent fleets grow, the organizational challenge shifts from “how do we get agents to work?” to “how do we manage a fleet of semi-autonomous systems reliably?”
Cross-Organizational Agent Protocols
MCP and A2A are laying the groundwork for agents to collaborate not just within an organization, but across organizations. An agent at a law firm and an agent at a client company exchanging work products through a standardized protocol, with appropriate authorization and audit trails on both sides. This is a few years out from being routine, but the protocol work is happening now.
The Economics Keep Shifting
One data point worth sitting with: the tasks-per-dollar number for frontier models varies by roughly 5–6x between the most capable and most cost-effective options available today. As the quality gap between top-three providers narrows to 3–7 percentage points on most benchmarks, cost becomes the decisive factor for high-volume workloads. The implication: smart routing — sending high-stakes queries to the best model and high-volume routine queries to cheaper alternatives — becomes not just a nice optimization but a significant cost lever.
Honest Verdict
Agentic workflows are genuinely one of the most significant shifts in enterprise software in a decade — not because of the AI alone, but because of what happens when reliable reasoning gets combined with the ability to act in digital environments. The real-world results, from Klarna to JPMorgan to Ford, are no longer aspirational. They’re production numbers.
At the same time, the failure rate is real. Roughly 19% of deployments never reach payback, and Gartner projects 40% of projects will be abandoned by 2027. The causes are almost always preventable: wrong workflow chosen, data not clean enough, no evaluation infrastructure, governance treated as an afterthought. The organizations doing this well are treating it as a fundamental change to how work gets done — not a tool to test.
The honest position is neither cynicism nor uncritical enthusiasm. Agentic workflows work, the economics are improving rapidly, and the window for building meaningful competitive advantage through early deployment is still open — but narrowing. Organizations that invest in the foundations now (data quality, evaluation, governance) will outperform those that either sit on the sidelines or rush into production without the supporting infrastructure.
Sources & Further Reading
- MIT Sloan Management Review / BCG — Agentic AI Explained (Feb 2026)
- Deloitte Insights — Agentic AI Strategy (Feb 2026)
- Google Cloud — ROI of AI: Agents Delivering for Business (2025)
- Gartner — Predicts 2026: AI Agents in Enterprise Applications
- Bain & Company — Agentic AI Benchmark 2026
- McKinsey Global AI Survey 2026
- Dataiku — Agentic Workflows Guide (2026)
- Microsoft Community Hub — Building High-Performance Agentic Systems (Mar 2026)
- AI Monk — 12 Agentic AI Examples with Measurable ROI (2026)
- G2 — Enterprise AI Agents Report (2026)
- IntuitionLabs — Agentic AI and Temporal Orchestration (2026)
- Forrester TEI Studies — Customer Service and Engineering Agent Economics (2026)
- MIT AI Agent Index 2025 — aiagentindex.mit.edu
- OWASP / ATLAS — Agentic AI Threat Models
- Salesmate — The Future of AI Agents: Key Trends to Watch (2026)
More from Trendix.tech
AI Agent Use Cases by Business Function:The 2026 Prioritization Guide
AI Workflows & Automation:The Complete 2025–2026 Guide
AI Agent Governance:A CISO’s 2026 Checklist
AI Agents & Multi-Agent Systems: The Definitive 2026 Guide
Human-in-the-Loop AI: The Complete Production Implementation Guide
AI Agents & Multi-Agent Systems: Everything Changes This Year
MCP + A2A Protocol: The Complete Architecture Guide
The Comprehensive Ranking: Best AI Tools 2026
AI Industry Applications: The Definitive 2026 Field Guide
The Voice & Video AI Revolution:Everything That Matters in 2026